STEM Synapse

Subjects

AI & Machine Learning

Today

  1. Paper of the DayPreprint, not yet peer reviewed

    Fast Catch-Up, Late Switching: Optimal Batch Size Scheduling via Functional Scaling Laws

    Language models are trained on data fed in batches, and how large those batches should be at each stage is usually set by rule of thumb.

    Why it matters Language models can be trained on small batches for most of the run and switched to large ones late, saving data without losing quality.

    The researchers used a mathematical description of how training error falls over time to find the best batch-size schedule when the amount of data is fixed. For easy tasks the batch should keep growing; for hard ones it should stay small for most of training and jump to large only near the end. After that late switch the model quickly catches up, because the noise built up from small batches fades fast. Tests on models of up to 1.1 billion parameters showed late switching beat constant and early-switch schedules while using less data.

    Wang et al., arXiv cs.AI, 17 November 2026.
    Read the paper: Fast Catch-Up, Late Switching: Optimal Batch Size Scheduling via Functional Scaling Laws

Tuesday 17 November

  1. Paper of the DayPreprint, not yet peer reviewed

    PhysDox: Benchmarking LLMs on Physical Feasibility Auditing of Physiological Sensing Protocols

    Language models are increasingly asked to help design experiments, and they write plans that read well, yet a fluent plan can still be physically impossible to carry out.

    Why it matters Language models that help plan lab work often miss the physical reasons a written experiment cannot succeed, especially limits nobody states outright.

    The researchers built a test of 683 expert-checked plans for measuring signals from the human body, each graded as sound, slightly flawed or fatally flawed, and asked six models to judge them. The best reached a score of only 53 out of 100 at spotting the problems. The models tended to mistake a plan that lists every step for one that would work, and they missed unstated physical limits about twice as often as plain hardware errors. The authors conclude that checking feasibility takes real physical reasoning rather than recall.

    Liu et al., arXiv cs.AI, 16 November 2026.

    Read the paper: PhysDox: Benchmarking LLMs on Physical Feasibility Auditing of Physiological Sensing Protocols

Monday 16 November

  1. Paper of the DayPreprint, not yet peer reviewed

    Goal Encoding in LLMs

    When a language model works through a task with several steps, does it hold a goal internally before it acts?

    Why it matters A language model's next intended step can be located in a few internal components, read out in plain words, and transplanted to trigger the same action.

    The researchers gave models coding tasks made of several sub-tasks and looked inside. They found the next sub-goal recorded in the output of a small set of attention heads, the components a model uses to pull in information from earlier text, and could read it out in plain words. Moving that signal into a different setting, such as another programming language, triggered the same operation there. Because such a model cannot carry an internal state forward for long, the authors propose that it keeps re-reading the goal from its instructions and checking progress, an idea they test with targeted experiments.

    Sharma et al., arXiv cs.AI, 12 November 2026.

    Read the paper: Goal Encoding in LLMs

  2. Paper of the DayPreprint, not yet peer reviewed

    Negative-Only Policy Optimization for One-Sided Verifiable Rewards

    One way to train AI models is to let them attempt problems and reward the answers an automatic checker confirms as right.

    Why it matters AI models can be trained to improve even when automatic checks can only catch wrong answers and never confirm right ones, by learning from the failures alone.

    In many real cases no such checker exists: cheap tests, like a handful of unit tests for code, can prove an answer wrong but cannot prove it right. Rewarding everything that passes then teaches the model shortcuts that slip through the tests. The authors propose learning only from answers known to be wrong: the model is steered away from confirmed failures, and answers that pass are treated as unknown. On coding, logic and maths benchmarks the method solved more problems than existing approaches, and the gain held when it was carried over to other benchmarks.

    Xu et al., arXiv cs.LG, 12 November 2026.

    Read the paper: Negative-Only Policy Optimization for One-Sided Verifiable Rewards

Sunday 15 November

  1. Paper of the Day

    Weisfeiler-Lehman Meets Optimal Transport: Theory, Algorithms, and Implications

    How do you measure how different two networks are?

    Why it matters Graph-based machine learning gains a measure of how different two networks are that is quick to compute and agrees with a classic test for telling them apart.

    A classic test, named after Weisfeiler and Lehman, answers only yes or no: it checks whether two networks can be told apart by repeatedly comparing each point's neighbours. This paper turns the test into a distance, a number saying how far apart two networks are, which is zero exactly when the test cannot tell them apart. The distance can be computed efficiently and picks up finer differences than a leading existing method. From it the authors design a type of neural network that can, in principle, learn any continuous function of networks. The distance also turns out to be linked to a branch of mathematics about moving probability distributions.

    Chen et al., JMLR, 14 November 2026.

    Read the paper: Weisfeiler-Lehman Meets Optimal Transport: Theory, Algorithms, and Implications

Saturday 14 November

  1. Paper of the Day

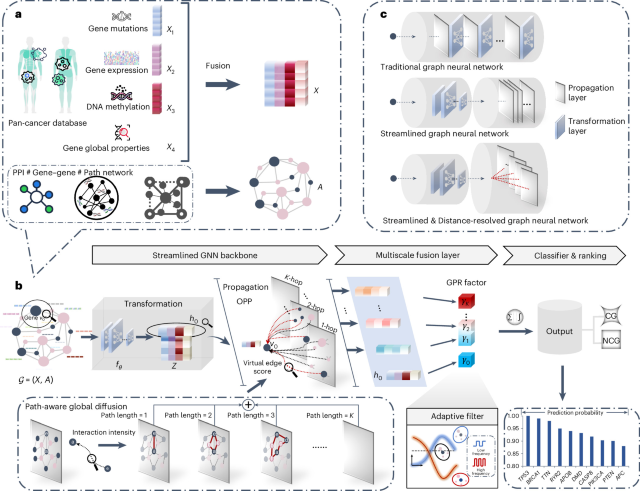
    Multimodal cell foundation models require synergistic integration beyond alignment

    Biologists have AI models trained on single kinds of cell data, such as microscope images of tissue or readouts of which genes are active.

    Why it matters Combining tissue images with gene activity data helps only when the pair reveals what neither shows alone, and common methods often miss exactly that.

    Datasets pairing both kinds are scarce, so a common shortcut joins two ready-made models. Does the pair reveal anything the stronger model did not know? The authors introduce a score for the information that appears only when the two kinds of data are considered together. They show that the usual way of joining models mostly picks up what the two already share and misses what only the pair reveals. Across ten joining methods, a single model was enough for simple tasks, while defining complex cell neighbourhoods gained from methods built for the extra information.

    Richter et al., Nature Machine Intelligence, 9 November 2026. doi:10.1038/s42256-026-01328-3

    Read the paper: Multimodal cell foundation models require synergistic integration beyond alignment

Friday 13 November

  1. Paper of the DayPreprint, not yet peer reviewed

    Unbundling Multimodal Vision Encoding

    AI models that work with both images and text differ in how they take in a picture.

    Why it matters Models that handle images and text did not need a vision component trained in advance, only a part of the model devoted to images, in a matched comparison.

    Most pass it through a separate vision component trained beforehand; some train that component together with the language model, and some drop it. Published models also differ in data, design and computing budget, so comparing them cannot show which choice matters. Here every model was trained from scratch on the same data with the same computing budget. A vision component trained jointly did as well as a pre-trained one, so the advance training was not needed. What mattered was having part of the model devoted to vision: models without it fell behind even when enlarged to match.

    Brown et al., arXiv cs.LG, 12 November 2026.

    Read the paper: Unbundling Multimodal Vision Encoding

Thursday 12 November